文献综述AI率检测实测:引文逐条核对
我们用 Humanizer v2 处理了一段 AI 起草的文献综述。所有引文都完整保留,但引文所支撑的部分论断发生了偏移。
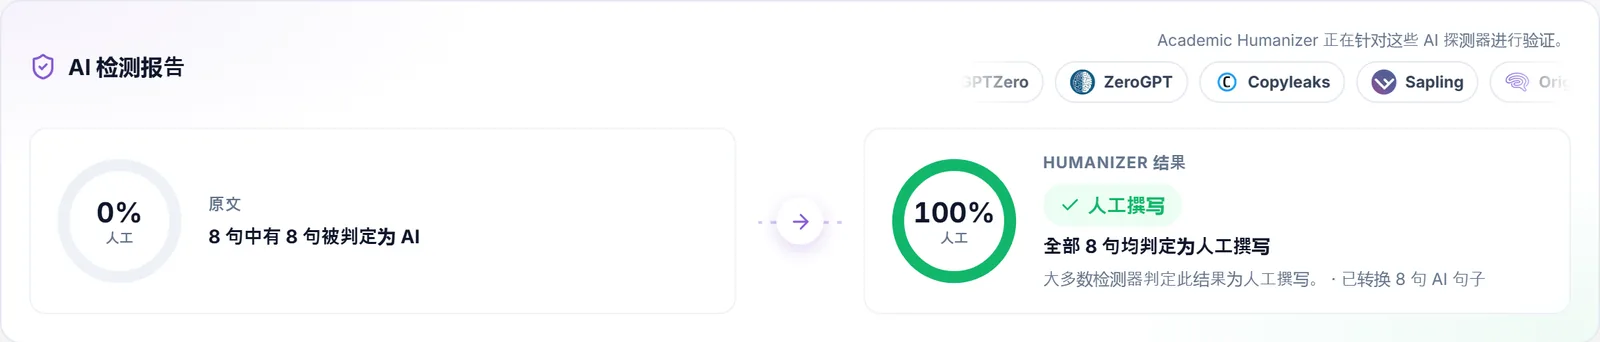
AI 检测器能查出 AI 起草的文献综述吗?在我们的测试中,无一例外都查出来了:草稿上五个检测模型全部判为 AI,八个句子全部被标记。这段文字来自教育学研究,我们用 Humanizer v2 处理了它。处理后,五个模型中有四个判为人写,每个句子都被判为人写,四组引文全部完整保留。
引文保住了。但引文所支撑的部分论断并没有原样保留,这正是值得仔细读的部分。
为什么文献综述的文字容易被标记
文献综述段落有一个可预测的结构:领域在发展,研究表明有益处,效果因情境而异,某个较新的方向值得关注,仍存在空白,需要进一步研究。语言模型能流畅地复现这个结构,而且每次都用同样的连接词来装点。我们的草稿用 "In recent years"、"However"、"For instance"、"Moreover"、"Despite these advances" 和 "Consequently" 开头,还用了 "garnered considerable attention" 和 "a pressing need"。
In recent years, the integration of formative assessment practices into higher education has garnered considerable attention from researchers and practitioners alike. Numerous studies have highlighted the potential of formative feedback to enhance student learning outcomes, foster self-regulated learning, and promote deeper engagement with course content (Black & Wiliam, 1998; Nicol & Macfarlane-Dick, 2006). However, the effectiveness of such practices is not uniform across contexts. For instance, Hattie and Timperley (2007) emphasized that the impact of feedback depends heavily on its focus, timing, and the extent to which it addresses the gap between current and desired performance. Moreover, recent scholarship has increasingly recognized the role of student feedback literacy in determining whether feedback is actually used (Carless & Boud, 2018). Despite these advances, a notable gap remains in understanding how large-enrollment courses can implement formative assessment at scale without overburdening instructors. This gap is particularly salient in the context of introductory STEM courses, where class sizes frequently exceed several hundred students. Consequently, there is a pressing need for research that examines scalable, technology-supported approaches to formative feedback in such settings.
我们测试运行的真实扫描结果。八个句子全部被标记为 AI。就连 "However, the effectiveness of such practices is not uniform across contexts"(然而,这类做法的效果因情境而异)这样简短朴素的句子也被标记了。检测器不仅读词汇,也读段落的节奏;一连串结构整齐的句子,会把其中每一句都推向 AI 那一侧。
运行过程
- 扫描 AI 信号八个句子全部被标记;五个模型全部判为 AI。
- 改写被标记的句子八个句子全部改写,引文都被带入新句子中。
- 用 AI 检测器复查八个句子现在全部被判为人写;五个模型中四个判为人写。
- 保存结果1,320 个字符,按每 500 个字符 1 点向上取整:3 点。
- AI 起草的段落5 / 5
- Humanizer v2 输出1 / 5
引文保住了吗?
全部保住了,一个字符都没变。这在综述里比在其他任何地方都重要,因为年份写错、漏掉合著者这类错误,会让熟悉该领域的审稿人对你失去信任。
| 引文 | 是否保留在输出中? | 引文周围的变化 |
|---|---|---|
| Black & Wiliam, 1998 | 是,未改动 | 所支撑的论断中 "potential"(潜力)变成 "efficacy"(功效) |
| Nicol & Macfarlane-Dick, 2006 | 是,未改动 | 与上一行同一句 |
| Hattie and Timperley (2007) | 是,未改动 | "Emphasized"(强调)变成 "found"(发现);"addresses the gap"(弥合差距)变成 "highlights the gap"(突出差距) |
| Carless & Boud, 2018 | 是,未改动 | 术语 "feedback literacy"(反馈素养)被删掉 |
所以参考文献是安全的。需要你检查的是归属:引用某篇文献,就等于承诺这篇文献确实说了你的句子所说的内容。如果检测器标记的是参考文献列表本身,那是另一个问题,见参考文献被 Turnitin 判为 AI 的原因。
限定语气发生了什么变化
文献综述中的限定语气不是装饰。"Highlighted the potential"(指出了潜力)和 "shown the efficacy"(证明了功效)对证据的表述完全不同,你所在领域的读者一定会注意到你选了哪一个。
改写前
Numerous studies have highlighted the potential of formative feedback to enhance student learning outcomes, foster self-regulated learning, and promote deeper engagement with course content (Black & Wiliam, 1998; Nicol & Macfarlane-Dick, 2006). For instance, Hattie and Timperley (2007) emphasized that the impact of feedback depends heavily on its focus, timing, and the extent to which it addresses the gap between current and desired performance. Moreover, recent scholarship has increasingly recognized the role of student feedback literacy in determining whether feedback is actually used (Carless & Boud, 2018).
改写后
Many studies have shown the efficacy of formative feedback in improving student learning, facilitating self-regulated learning and enhancing students’ engagement with the course material (Black & Wiliam, 1998; Nicol & Macfarlane-Dick, 2006). Hattie and Timperley (2007), for example, found that the effectiveness of feedback varies based on its focus, timing, and whether it highlights the gap between current and desired performance. More recently, there has been a growing literature that links feedback effectiveness to the ability of students to interpret feedback (Carless & Boud, 2018).
以审稿人的眼光来看,这些变化可以分为三类。
- 论断变强了。"Highlighted the potential" 变成了 "shown the efficacy"。草稿原来的措辞更谨慎,而在概述一批研究时,谨慎通常是更稳妥的立场。
- 归属动词变了。Hattie 和 Timperley 的论文是一篇构建反馈模型的综述。"Emphasized" 与之相符;"found" 则暗示这是一项实证结果。而且 "addresses" 差距的反馈和 "highlights" 差距的反馈并不相同:前者是弥合差距,后者只是指出差距。
- 术语丢了。"Student feedback literacy"(学生反馈素养)正是 Carless 和 Boud 广为人知的概念。改写把它转述为学生 "ability to interpret feedback"(解读反馈的能力),而 "whether feedback is actually used"(反馈是否真正被采纳)也变成了“解读”。引用这篇论文的作者,会希望把这个术语改回来。
研究空白陈述发生了什么变化
最后三句承载了这段话的论证:缺什么,在哪里重要,需要什么。其中有两处细节发生了偏移。
- "Class sizes frequently exceed several hundred students"(班级人数常常超过数百人)变成了 "many classes have over a hundred students"(许多班级超过一百人)。这是事实层面的弱化。如果你的研究动机建立在超大班级上,请改回来。
- "How large-enrollment courses can implement formative assessment at scale without overburdening instructors"(大规模课程如何在不加重教师负担的前提下规模化实施形成性评价)变成了缺乏关于 "in large enrolling courses" 实施的研究。教师工作量这个角度,也就是真正的研究空白,不见了,而且 "large enrolling courses" 这个说法很别扭。
这里还有点讽刺意味。改写引入了 "one crucial limitation" 和 "significant differences",这两个词都是细心的编辑会删掉的。尤其是 "significant",在教育学论文中可能被误读为统计学上的显著。可检测器还是把这些句子判为人写,这说明扫描结果和文风规范是两回事。
改写后文献综述的复核流程
- 对照文献管理软件核对每一条引文:作者、年份、标点。
- 针对每个引用句,问自己:被引文献真的说了新版本所说的内容吗?最需要注意的是动词:found、showed、argued、emphasized、suggested。
- 把被转述掉的学科术语改回来。有名称的概念,正是把你的综述与文献联系起来的纽带。
- 比较数量和范围词("several hundred"、"at scale"、"without overburdening instructors")。
- 投稿前查看所在机构或期刊的 AI 政策。
我们的指南AI 辅助研究中的引用习惯和保持学术术语完整对每个步骤有更深入的说明。
结论
在检测方面,这次运行达到了文献综述作者想要的效果:八个被标记的句子全部被判为人写,引文完好无损。在含义方面,它产出的稿件大约需要集中修改五处措辞。只要这一步修改确实做了,这就是一笔划算的交换。
Academic Humanizer 正是围绕这一步修改而设计的。AI Detection Report 把每个原句和改写后的句子一一对齐,让你可以逐对检查归属和限定语气,而不用肉眼对比两段文字。
保留你的想法,去除 AI 痕迹
粘贴草稿,查看哪些句子被 AI 检测器标记,然后只用 Humanizer 改写这些句子。
免费试用 Humanizer